dyslectric.dev
  • Communities
  • Multi-communities
  • Support Lemmy
  • Search
  • Login
  • Sign Up
Technology@lemmy.worldbybeep@piefed.world
3 days

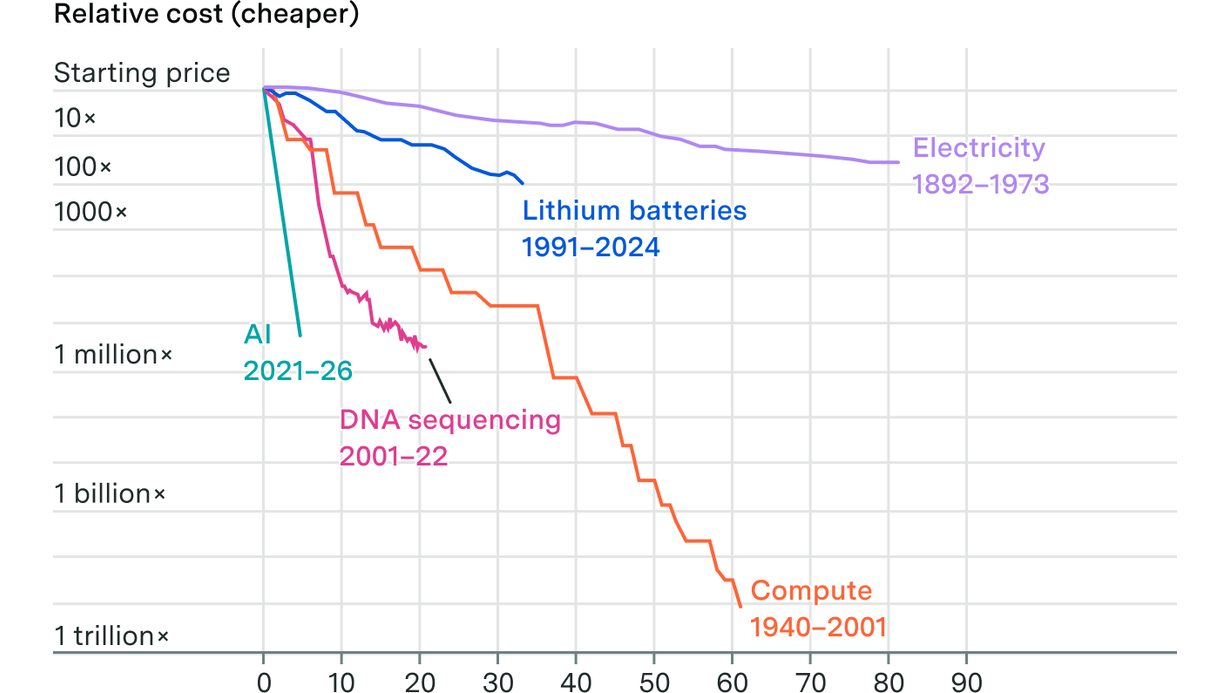
The price of AI is crashing faster than the rate of Moore's Law — intelligence costs are in freefall, outpacing comparative technologies like compute, DNA sequencing, and lithium batteries

epoch.ai English

cross-posted from: https://piefed.world/c/tech/p/1434965/the-price-of-ai-is-crashing-faster-than-the-rate-of-moore-s-law-report-suggests-intellig

68
    The plunging price of thought
    epoch.ai
    Epoch AI measures how fast the cost of a given level of AI performance is falling across five benchmarks covering math, science and games of skill: about 47% per quarter, or 13x per year, since 2023, faster than electricity, compute, batteries or DNA sequencing ever fell.
    You must log in or register to comment.

    • Kaligalis@lemmy.worldEnglish
      1 day

      Yeah. Not a surprise.

      everyone has bet on AI getting good enough to fully replace humans fast. CEOs mandated use of AI. The results weren’t as great as expected. CEOs started limiting AI use to counter the token cost explosion after employees found out how to waste tokens fast.

      At the same time, China’s AI development is driven by the party instead of companies. They aren’t so much interested in money as they are in the strategic solution to the demographic problem caused by the one-child policy (which worked a bit too well too fast). The companies there plan on making money by providing the compute (they literally have the power and a two digit number of nucular GW under construction right now).
      So their models are almost as good as US ones and freely downloadable to run on whatever hardware you want. That naturally limits the longterm-achievable AI token prices to little more than the cost of just providing the raw compute.

      US AI companies are also in a cut-throat competition for customers right from the start. That obviously doesn’t help to keep prices high. Currently, they all burn money so fast that it’s hard for a human mind to comprehend.
      None of the US AI companies will survive the next decade if they don’t actually are the only one making AI actually able to fully replace human workers. They will all go bankrupt and might take the whole US economy with them.
      Nvidia will probably be the real winner if they don’t fuck this up somehow (not sure if that is even possible) because they are the ones selling the shovels in this gold rush.

      In two decades, it will be normal to have the capabilities of current frontier models running locally on your Chinese phone.

        • Siru@discuss.tchncs.deEnglish
          18 hours

          The only thing I would add to this is that (in my understanding) Nvidia is largely selling future GPU manufacturing capacity to the large AI providers. So, if the providers end up going belly up, thrn Nvidia might take heftly losses from that as well.

        • naught101@lemmy.worldEnglish
          3 days

          the price of thought

          Oh fuck off.

            • blackshirt@lemmy.worldEnglish
              3 days

              These fuckers would sell us air if they could.

                • Agent641@lemmy.worldEnglish
                  2 days

                  I saw it in a documentary called Total Recall

                    • W98BSoD@lemmy.dbzer0.comEnglish
                      1 day

                    • nailingjello@piefed.zipEnglish
                      3 days

                    • latetolemmy@lemmy.worldBanned from communityEnglish
                      2 days
                  • solrize@lemmy.mlEnglish
                    3 days

                    How about DRAM? Show me some AI price crashes leading to DRAM price crashes. That’s what we all want, I think.

                      • WhatAmLemmy@lemmy.worldEnglish
                        3 days

                        This still applies.

                        Surveillance fascism needs the RAM, compute, and storage to implement totalitarianism and autonomous killing machines that won’t refuse to genocide the proles once they realize climate change is significantly worse than advertised, and our “democracies” are an illusion controlled by a big club of plutocrats.

                        When the AI bubble pops, the US government will bail out all the tech companies, and all of the debt will be transferred to the working class via our retirement account losses and inflation; no different to the trillions in “forgiven” corporate loans central banks around the world printed during covid. The working class will essentially pay for the nazi big brother and nazi skynet that enslaves them.

                        Thanyou for coming to my conspiracy theory ted talk.

                          • trashboat@piefed.socialEnglish
                            3 days

                            I’ve been starting to think that once the bubble begins to pop, the US will bail out the banks by buying up their loans to hyperscalers, and they’ll start writing giant surveillance contracts to AI companies to compensate for the lack of demand. The rich get richer and the resulting stock corrections will end up hurting regular people most

                              • WhatAmLemmy@lemmy.worldEnglish
                                3 days

                                Yeah, whether they buy the excess hardware in a fire-sale, nationalize open AI/Anthropic into the DoD on nat sec grounds, or just sign several hundred billion dollar contracts with them, we’re just splitting hairs. The threat and their intentions remain the same.

                          • CompactFlax@discuss.tchncs.deEnglish
                            3 days

                            “Look how low our cost of inference is”

                            “Pay no attention to the marketing budget that exceeds Coca-Cola’s for a small fraction of their revenues”

                            What technical, fundamental reason is there for the crash in price? The article just accepts the MSRP as fact. It’s established fact that retail prices can be dropped below cost in order to establish market dominance. The cost of training can indeed be spread over time but it’s not spread across enough time (between model releases)The inference cost doesn’t actually drop in reality.

                              • humanspiral@lemmy.caEnglish
                                18 hours

                                What technical, fundamental reason is there for the crash in price?

                                Smaller models are inherently faster, and use less gpus to fit inside, and less gpu time per training step. Newer models are smarter at smaller size than older models, and so also come up with correct answer in fewer tokens.

                                There are 15 labs accross the world competing without patent restriction for software building. It’s orders of magnitude faster than Moore’s law, because its highly competitive, and software has massive “compiler” resources thrown at it, in investor/government frenzy.

                                • pageflight@piefed.socialEnglish
                                  3 days

                                  Let’s just quickly check https://isaiprofitable.com/ :
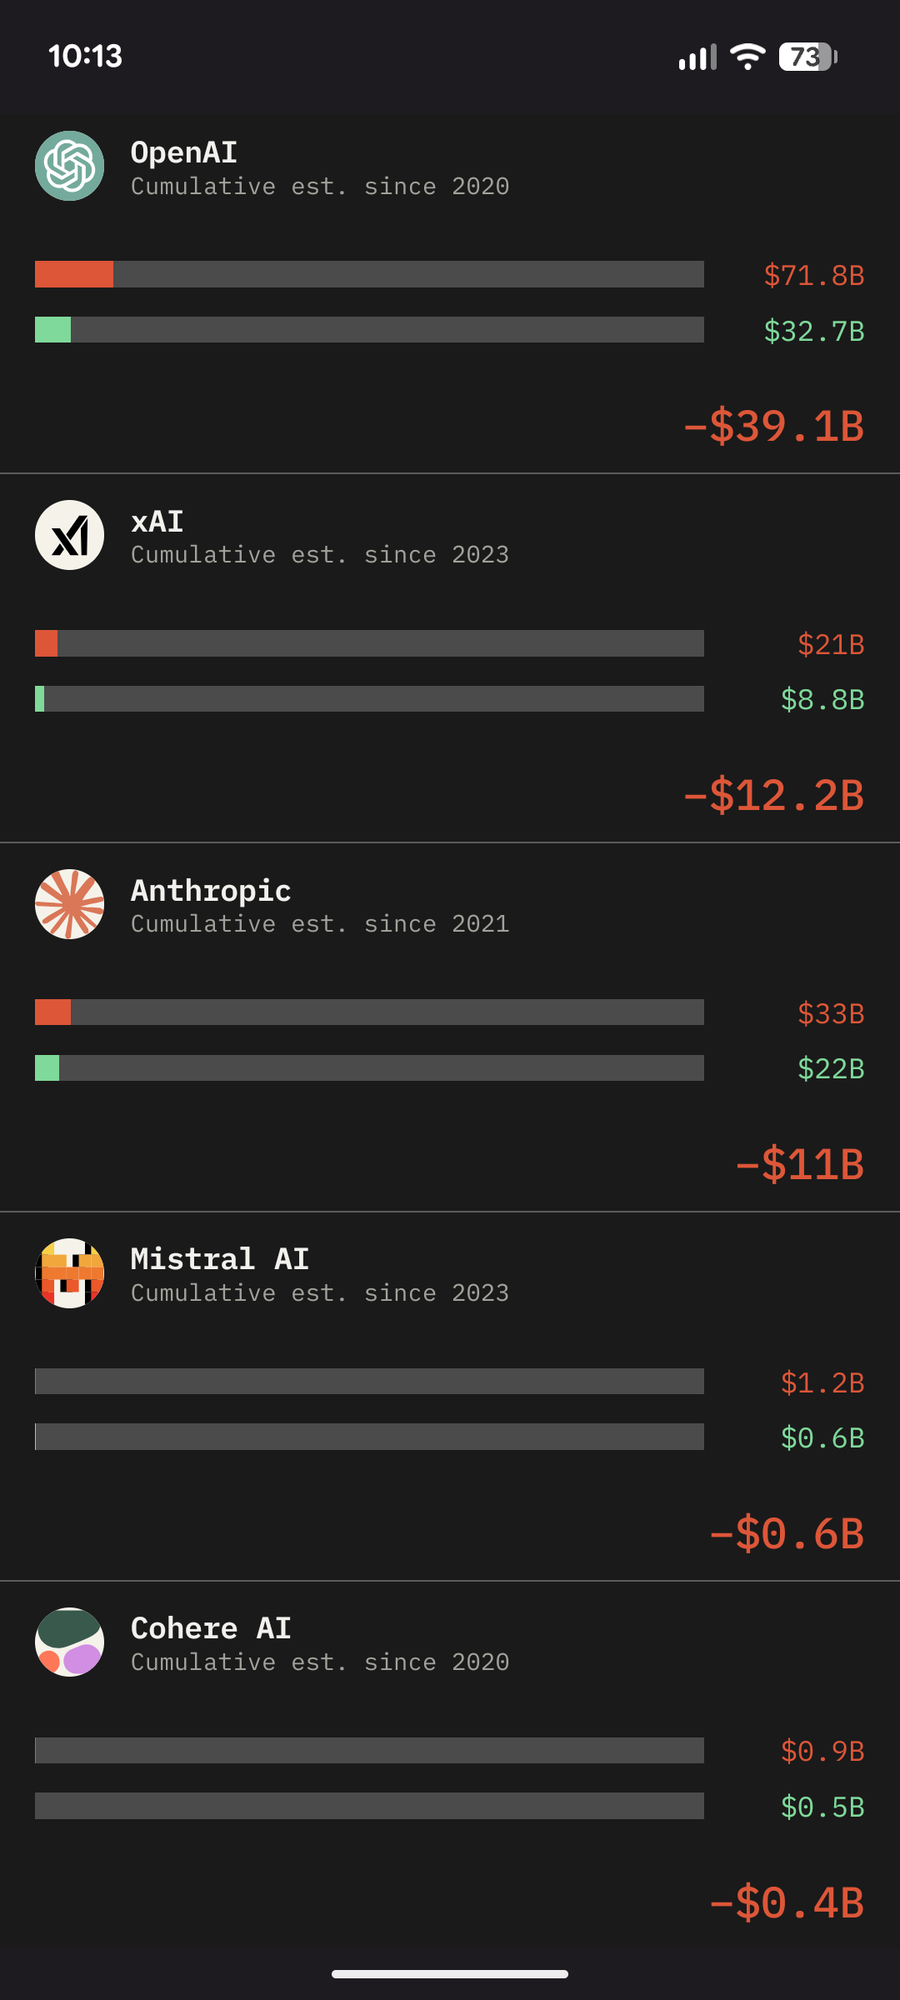
                                  nope

                                  Nope. The answer is still “they’re burning cash.” Only the companies making silicon are raking it in.

                                  • Grimy@lemmy.worldEnglish
                                    3 days

                                    There are constantly new techniques being developed to speed up inference or reduce model size post training. There’s about a hundred different levers to pull that play on inference cost, and some of them don’t have much of an impact on quality.

                                    In the end, it’s probably simply because of competition. I don’t understand why everybody assumes they are running these at cost API wise.

                                    Edit: here’s a chart from ars technica. The cost of revenue is clearly lower than the actual revenue. They aren’t running inference at a lost or it would be higher. They aren’t profitable because they are spending all that money on capturing the market as quick as they can. For fucks sake, that includes all the free accounts as well running inference. How can anyone think a paying customer is getting it at less than cost?

                                    And yes, there have been advancement made. The cost of inference isn’t some static number that can never go down. Stop believing them when they tell you there’s no profit to be made. It’s the same playbook as a dozen other companies, they literally get rewarded for it when it comes tax time.

                                      • Jiral@lemmy.worldEnglish
                                        3 days

                                        Yet all major players are still incapable of covering their costs and have to resort to all sorts of nasty accounting tricks to make it apear otherwise. How so?

                                          • Grimy@lemmy.worldEnglish
                                            3 days

                                            Because of the massive investments into datacenters. Why is everyone so quick to drink the kool-aid. They are spending stupid amounts of money to capture the market and force everyone into a subscription service, not because it cost money to actually run the models. They are all switching their models to fine tuned quants after the first two weeks as well.

                                            The open source community has found dozens of ways to lower costs, do you really think these big companies aren’t using the same tricks and haven’t developed even more advanced techniques?

                                              • Jiral@lemmy.worldEnglish
                                                3 days

                                                It doesn’t matter what tricks they supposedly use afterwards, the data centets that are built need to run successfully or the bubble pops and then those companies will fall like lead. In other words for those data centers to be successfull the entire real economy has to spend crazy amounts of money on stuff that needs crazy amounts of compute.

                                                Open AI and Anthropic would really need some good business numbers, right now. The claim that they are just deliberately making their business case much worse than it is, is insane.

                                                  • Grimy@lemmy.worldEnglish
                                                    3 days

                                                    The inference cost doesn’t actually drop in reality.

                                                    My comment was about this which is just completely wrong.

                                                    OpenAI is the scummiest company on earth but everyone is ready to believe them when they say shit like "our 20$ plan lets you run up the equivalent of a billion dollars in API fees. Giggles. It’s a good plan for you but not for us ;) "

                                                    The main thing bringing up costs is stuff like Sam Altman spending all the “inference” money on raw wafers just to strangle consumer GPU sales.

                                                    It’s not a good business model because of how cheap inference actually is. Once you have open models and the moat is broken, the only thing left to do is regulatory capture, upping the demand for the hardware and little charades like these.

                                          • Eq0@literature.cafeEnglish
                                            3 days

                                            Extremely interesting… so the depreciation of older models is extreme, while new models are constantly presented. And all the while no AI company is making any profit. This whole story is bonkers

                                              • sorter_plainview@lemmy.todayEnglish
                                                3 days

                                                The catch is

                                                the cost of a given level of AI performance

                                                And more interestingly the article itself says this

                                                And to this extent, when comparing price drops for AI to drops for other technologies for which we have price series, we are comparing apples and oranges.

                                                Even then, they decided to make it the headline. This is just like LLM bros doing things they don’t know anything about. Absolute garbage.

                                                • bcgm3@lemmy.worldEnglish
                                                  3 days

                                                  Hadn’t you heard? Some day, one of these things is gonna cure cancer. We all just gotta kill ourselves subsidizing it until then!

                                                • Coriza@lemmy.worldEnglish
                                                  2 days

                                                  The other day I saw a video talking about this new innovation on LLM inference side of things where they keep some more used weights in RAM and others less used on disk. I always suspected from the sample code I stumbled upon on the IA world that should be extreme opportunities for optimizations. But I cannot stress it enough how dumb the LLM world is where the basics of implementing an LRU cache is pass of as some big innovation. Like any half competent comp-sci or comp-eng professional know about the basics of mitigating this basics bottlenecks like “the data does not fit on available RAM”, “The disk is slow”, etc.

                                                  So is not surprising that now that it seems that the “powerfulness” of this LLMs is starting to plateau that we would start to see some improvement in performance/resource utilization and hence running costs.

                                                    • KingRandomGuy@lemmy.worldEnglish
                                                      1 day

                                                      Keep in mind many of the optimizations you’re talking about (LRU caching of experts, for example) are only really relevant at the single user local inference scale. As in, an individual wants to run a big model on their machine, but they don’t have enough VRAM to fit the model and KV cache. Accordingly, you’re basically only describing hobbyist and research projects, which aren’t really representative of the AI inference industry as a whole.

                                                      Commercial inference keeps everything resident in VRAM, so expert caching isn’t necessary. So these things won’t help costs. A lot of other low hanging fruit (like hierarchical KV cache) has also existed for a long time for production-ready inference engines.

                                                        • Coriza@lemmy.worldEnglish
                                                          1 day

                                                          I am not sure it would not help commercial solutions, if all experts are used all the time, sure, but if for example the usage is biased for some experts it would enable one machine to serve more users in parallel or save on VRAM or DRAM without compromising response time, hence cutting costs.

                                                            • KingRandomGuy@lemmy.worldEnglish
                                                              15 hours

                                                              It still won’t help for a couple of reasons. For one, VRAM is fairly abundant on commercial deployments. Even for big models, a company is probably deploying on 1-2 nodes of 8x H200 or newer (hence several TB of VRAM).

                                                              But more importantly, commercial inference relies on heavy concurrency. So even if some experts are uncommon, with a lot of concurrent users, they will still fire frequently enough for the performance difference to be felt. And in my own experience, expert use isn’t uniform but it isn’t particularly biased either. This is especially tough since high-concurrency inference can actually be fairly compute bound, but this expert caching system either starves the system of bandwidth (if you require compute on the GPU, then you’re stuck with PCIe speeds which are tiny compared to HBM and even DRAM), or you’re starved of compute (if you do compute on the CPU).

                                                              It’s nice for local inference, but yeah, not representative of commercial inference.

                                                          • wewbull@feddit.ukEnglish
                                                            2 days

                                                            That works for “Mixture of Experts” models. These are basically models with distinct sets of weights and only a subset of them will be used on any particular query. The rest can sit on a disk.

                                                            It doesn’t work for dense models, where every weight is used all the time. There’s nothing inactive so a cache has nothing to exploit.

                                                              • Coriza@lemmy.worldEnglish
                                                                1 day

                                                                Yes, I believe it was for a Mixture of experts model, which just goes to show how naive IA implementations are at this point, The cache was not solving any hard problem and yet for some reason it was not only not already standard practice but also somehow a notable achievement.

                                                            • Treczoks@lemmy.worldEnglish
                                                              3 days

                                                              I wonder how they plan to match “prices are in free fall” to “the AI industry will have to make trillions a year in order not to go bust”.

                                                              On the other hand, “prices in free fall” might be the answer they got from AI…

                                                                • MoffKalast@lemmy.worldEnglish
                                                                  3 days

                                                                  At this point the cloud model firms are basically banking on making a superinteligence before anyone else and taking over the planet, otherwise they go bankrupt. I wish I was kidding.

                                                                  Nvidia wins either way though, local models, cloud models, shovels always sell. So they have that overvalued but still realistic bedrock to build houses of cards on.

                                                                    • Quazatron@lemmy.worldEnglish
                                                                      2 days

                                                                      Nvidia wins unless some other company starts selling cheaper, faster, more efficient matrix multiplication machines.

                                                                      I’ve read some articles about radically different inference architectures that may tilt the scales, but I know this is wishful thinking because I really would like Nvidia to fail badly.

                                                                      Linus_nvidia.gif

                                                                        • MoffKalast@lemmy.worldEnglish
                                                                          2 days

                                                                          Plenty have tried, all have fallen over flat on their face when it comes to actually providing usable drivers or production at scale. AMD’s still completely half assing it even today and Intel’s OneAPI and Vino is a bloated joke.

                                                                          But yes I would love a future where AMD finally hires an actual software team.

                                                                    • Th4tGuyII@fedia.io
                                                                      3 days

                                                                      So in essence the price that the market will bare for the cost of AI usage is significantly lower than what the big AI companies would like it to be (in order to pay back their ever growing debts), which means there is a possibility they might never achieve profitability on their own (without some external/governmental strong-arming)

                                                                        • Slashme@lemmy.worldEnglish
                                                                          2 days

                                                                          *bear

                                                                            • Logi@lemmy.worldEnglish
                                                                              1 day

                                                                              Bare bears bore boars beer.

                                                                            • pageflight@piefed.socialEnglish
                                                                              3 days

                                                                              Yeah, I’d like to see the cost of sub-prime mortgage on that chart.

                                                                            • pulsewidth@lemmy.worldEnglish
                                                                              3 days

                                                                              It’s funny watching them rig the system and simultaneously keep shooting themselves in the dick.

                                                                              Nvidia - desperate not to lose business as they’re now ~93% dependent on AI sales, so they keep ‘investing’ in OpenAI, Anthropic, etc… Who turn around and of course immediately buy Nvidia AI chipsets.

                                                                              OpenAI and Anthropic - panicking that investors will realize their IP is worth nothing (what we’ve said all along) as they are overtaken by much cheaper models, so they lower their pricing drastically - can’t risk losing that market share*.

                                                                              *market share is irrelevant really, there is no first-to-market winner in AI, but you cant lie to idiots investors for another 16 rounds of funding to 2030 unless you can show userbase growth to them.

                                                                              Really hard to keep propping up the con when barely anyone is paying.

                                                                              Fingers crossed for horrible things to happen to then soon.

                                                                              • Chozo@fedia.io
                                                                                3 days

                                                                                That’s cool and all, but when can I buy RAM again?

                                                                                  • Kaligalis@lemmy.worldEnglish
                                                                                    1 day

                                                                                    Never if you are in the US. In a few years if you are allowed to buy Chinese.

                                                                                    • Rothe@piefed.socialEnglish
                                                                                      3 days

                                                                                      In 4 years or never. The latter probably being the most likely, since they are not just keeping RAM from you for AI purposes. They don’t want you to own you own hardware anymore, so they just simply stop manufacturing consumergrade hardware.

                                                                                        • Simon_Shitewood@lemmy.mlEnglish
                                                                                          3 days

                                                                                          Probably not never - CXMT are trying to aggressively expand to fill the market now the major players have left, but it will still be a few years before prices really come down as a result.

                                                                                          • corsicanguppy@lemmy.caEnglish
                                                                                            3 days

                                                                                            They don’t want you to own [your] own hardware anymore

                                                                                            Daily, it seems, I realize I’m one of the non-telepathic people: I can’t immediately know chip-maker company CEO motives and goals, and I just don’t see the conspiracy you do. What am I thinking right now?

                                                                                        • Setiyeti93@lemmy.caEnglish
                                                                                          3 days

                                                                                          Because those other technologies are infinitely more useful… So obviously governments and private equity you’re going to invest in AI. Makes perfect sense to me.

                                                                                          God I’m so tired

                                                                                            • REDACTED@infosec.pubEnglish
                                                                                              3 days

                                                                                              No one knows how useful AI will be in the long term and anyone thinking they know is full of themselves Everyone’s gambling.

                                                                                                • sheetzoos@lemmy.worldEnglish
                                                                                                  2 days

                                                                                                  It’s hilarious how many downvotes are given to an objectively true statement. People hate when echo chambers don’t confirm their biases.

                                                                                                  • Broadfern@lemmy.worldEnglish
                                                                                                    3 days

                                                                                                    Like the dotcom bubble, the technology will likely stay long term but the hype scam has been the major issue

                                                                                                    • Rothe@piefed.socialEnglish
                                                                                                      3 days

                                                                                                      It will have some uses. But it will not be the foundation of everything in future tech like they are claiming. It will be some limited mainstay markets, which doesn’t in any way justify the size of the hyperscaling they are trying to achieve. All that is pure posturing for the stock value.

                                                                                                      Especially since the open source models may likely win out over the big expensive corpo models, based purely on costs.

                                                                                                        • REDACTED@infosec.pubEnglish
                                                                                                          3 days

                                                                                                          So what about 5 years? Forget the LLMs, seemingly alot of positive things are happening in various industries thanks to advancements in AI (machine learning, robotics, etc). What about 10 years? What about 25? This is one of those things that will keep advancing, just like computers themselves.

                                                                                                          640K ought to be enough for anybody

                                                                                                        • DrSleepless@lemmy.worldEnglish
                                                                                                          3 days

                                                                                                          Yep I see polymarket and fan duel ads all the time, everybody is gambling

                                                                                                      • pHr34kY@lemmy.worldEnglish
                                                                                                        3 days

                                                                                                        Kinda sus that the cost of electricity stops at 1973.

                                                                                                        • humanspiral@lemmy.caEnglish
                                                                                                          2 days

                                                                                                          The cost decline for a given level of performance does tend to slow over time

                                                                                                          Even in their tests, there are big drops in 2026 models, and recent ones.

                                                                                                          A much more comprehensive and easy test is to follow this benchmark suite (AAi). Its a mix of medium/hard benchmarks, with bias for agentic coding. (sorry for url dump) https://artificialanalysis.ai/?endpoints=openai_gpt-5-2-codex%2Cazure_kimi-k2-thinking%2Camazon-bedrock_qwen3-coder-480b-a35b-instruct%2Camazon-bedrock_qwen3-coder-30b-a3b-instruct%2Ctogetherai_minimax-m2-5_fp4%2Ctogetherai_glm-5_fp4%2Ctogetherai_qwen3-next-80b-a3b-reasoning%2Cgoogle_gemini-3-pro_ai-studio%2Cgoogle_glm-4-7%2Cmoonshot-ai_kimi-k2-thinking_turbo%2Cnovita_glm-5_fp8&models=mimo-v2-5-pro%2Cgpt-6-sol-low%2Cgemini-3-5-flash-minimal%2Cgpt-5-6-luna-low%2Cclaude-fable-5-1-low%2Ckimi-k2-6%2Ckimi-k2-6-non-reasoning%2Cmimo-v2-0206%2Cglm-5-3-flash%2Cgpt-6-luna-xhigh%2Cglm-4.5%2Cgpt-5-5%2Cclaude-opus-5-low%2Cmimo-v2-5-0424%2Cclaude-sonnet-5%2Cmimo-v2-6-pro%2Cclaude-opus-4-5-thinking%2Cminimax-m3%2Cgpt-6-astra%2Cclaude-opus-5-5%2Cqwen3-8-27b-non-reasoning%2Cgpt-6-luna-medium%2Cclaude-fable-5-1%2Cgpt-5-6-luna%2Cmimo-v2-5-pro-non-reasoning%2Cminimax-m2-7%2Ck2-horizon-mova-36b-a4b%2Cclaude-opus-4-6-adaptive%2Cgpt-5-6-luna-medium%2Cgemini-3-1-flash-lite-preview%2Cgpt-5-4-pro%2Cgrok-4-3-medium%2Cnvidia-nemotron-3-super-120b-a12b%2Cgpt-6-luna-non-reasoning%2Cqwen3-8-27b-medium%2Cgpt-5-5-medium%2Cdeepseek-v4-pro-0424-non-reasoning%2Cgpt-6-luna%2Cgemini-3-8-flash-medium%2Cnvidia-nemotron-3-nano-30b-a3b-reasoning%2Cgrok-4-5%2Cgemini-3-flash-reasoning%2Cgpt-6-luna-high%2Cqwen3-8-27b-low%2Cmimo-v2-flash%2Cdeepseek-v4-pro%2Cqwen3-6-35b-a3b%2Cgemini-3-8-flash%2Cclaude-4-5-sonnet-thinking%2Cllama-4-maverick%2Cgrok-4-3%2Cclaude-opus-4-8%2Cmuse-spark-1-3%2Cqwen3-8-flash-next%2Cgpt-6-astra-low%2Ckimi-k2-5%2Cgpt-5-4%2Cqwen3-8-27b%2Cqwen3-8-max%2Cgpt-5-5-high%2Cclaude-sonnet-5-5%2Chy3%2Cclaude-opus-5%2Cgpt-5-4-mini%2Ck2-horizon-375b-a23b%2Cgemini-3-1-pro-preview%2Cgpt-6-luna-low%2Cgpt-6-sol%2Cgrok-4-6%2Cclaude-4-1-opus-thinking%2Cglm-5-3%2Cgpt-6-sol-non-reasoning%2Cclaude-sonnet-5-non-reasoning%2Cgpt-5-6-sol%2Cgpt-5-6-sol-xhigh%2Cdeepseek-v4-1-flash%2Cgemini-3-7-flash-low%2Cclaude-opus-5-5-xhigh%2Cclaude-sonnet-4-6-adaptive%2Cglm-5-2-non-reasoning%2Cclaude-opus-5-5-medium%2Cgpt-oss-120b%2Cclaude-opus-5-5-high%2Cglm-5-2%2Ckimi-k3%2Cgrok-4-3-low%2Cdeepseek-v4-flash%2Cclaude-opus-5-medium%2Cgemini-4-argon&agents=claude-code-fable-5-1-max-with-fallback%2Ckimi-code-cli-kimi-k3%2Cgrok-build-grok-4-7-xhigh%2Cmuse-code-muse-spark-1-3-max%2Cantigravity-sdk-gemini-3-8-flash-high%2Cdevin-fusion-cli-gpt-6-astra-xhigh-swe-2-medium%2Cclaude-code-qwen3-8-max%2Cdevin-fusion-cli-claude-fable-5-1-xhigh-swe-2-medium%2Ccodex-gpt-5-6-sol-max-reasoning-effort-max%2Cclaude-code-opus-5-max%2Ccodex-gpt-6-astra-max-reasoning-effort-max%2Copencode-glm-5-3-reasoning-effort-max%2Cgrok-build-grok-4-6-xhigh%2Ccodex-deepseek-v4-pro-0813-max%2Ccodex-deepseek-v4-flash-0731-max%2Cmuse-code-muse-spark-1-3-xhigh&coding-agents=cost&model-creators=zai%2Cgoogle%2Calibaba%2Copenai%2Canthropic%2Cxai%2Cmeta%2Cmistral%2Cdeepseek%2Cstepfun%2Cthinking-machines%2Ckimi%2Cifm%2Cminimax%2Cxiaomi&releases=claude-opus-5-5%2Cclaude-fable-5-1%2Cgpt-6-astra%2Cgpt-5-6-luna%2Cmuse-spark-1-3%2Cgrok-4-7%2Cmimo-v2-6-pro%2Cglm-5-3%2Cgemini-3-8-flash%2Cdeepseek-v4-1-flash%2Cminimax-m3&capability-models=gemini-3-5-flash-lite%2Cstep-5%2Cinkling%2Cmimo-v2-6-flash%2Cglm-5-3-flash%2Cmimo-v2-6-pro%2Cminimax-m3%2Cgpt-6-astra%2Cclaude-opus-5-5%2Cclaude-fable-5-1%2Cgpt-5-6-luna%2Cmuse-glimmer%2Cgrok-4-7%2Cnvidia-nemotron-3-ultra-550b-a55b%2Cgpt-6-luna%2Cgemini-3-8-flash%2Cmuse-spark-1-3%2Cqwen3-8-27b%2Cqwen3-8-max%2Cclaude-sonnet-5-5%2Cclaude-opus-5%2Ck2-horizon-375b-a23b%2Cgpt-6-sol%2Cglm-5-3%2Cgpt-5-6-sol%2Cdeepseek-v4-1-flash%2Cmistral-medium-3-5%2Ckimi-k3%2Cqwen3-8-flash-next&cost=evaluation-breakdown

                                                                                                          Opus 4.8 (may 2026), by far best model at the time, gets equaled by deepseek 4 pro (july 31) and 4.1 flash (sept 10th) at less than 1/100th the cost. MiMo 2.6 pro (sept 21) is even cheaper and beats opus 4.8 scores by a wide margin. sonnet 4.6 max to gpt luna high is also a 99% cost drop in a short time for lower performance level models.
                                                                                                          • exu@feditown.comEnglish
                                                                                                            3 days

                                                                                                            So instead of 1$ return for 3$ spent it’s now 4$ or 5$ spent.

                                                                                                            • floquant@lemmy.dbzer0.comEnglish
                                                                                                              3 days

                                                                                                              So also less revenue for the AI companies?

                                                                                                                • Rothe@piefed.socialEnglish
                                                                                                                  3 days

                                                                                                                  Yes, tiny as it is already.

                                                                                                                Technology@lemmy.world

                                                                                                                technology@lemmy.world

                                                                                                                Subscribe from remote instance

                                                                                                                Create post

                                                                                                                Report community

                                                                                                                Modlog
                                                                                                                You are not logged in. However you can subscribe from another Fediverse account, for example Lemmy or Mastodon. To do this, paste the following into the search field of your instance: [email protected]

                                                                                                                This is a most excellent place for technology news and articles.


                                                                                                                Our Rules


                                                                                                                1. Follow the lemmy.world rules.
                                                                                                                2. Only tech related news or articles.
                                                                                                                3. Be excellent to each other!
                                                                                                                4. Mod approved content bots can post up to 10 articles per day.
                                                                                                                5. Threads asking for personal tech support may be deleted.
                                                                                                                6. Politics threads may be removed.
                                                                                                                7. No memes allowed as posts, OK to post as comments.
                                                                                                                8. Only approved bots from the list below, this includes using AI responses and summaries. To ask if your bot can be added please contact a mod.
                                                                                                                9. Check for duplicates before posting, duplicates may be removed
                                                                                                                10. Accounts 7 days and younger will have their posts automatically removed.

                                                                                                                Approved Bots


                                                                                                                • @[email protected]
                                                                                                                • @[email protected]
                                                                                                                • @[email protected]
                                                                                                                • @[email protected]
                                                                                                                Visibility: Public

                                                                                                                This community is visible to everyone.

                                                                                                                3.22K users / Day8.51K users / Week10.5K users / Month10.6K users / 6 months504 posts10.9K comments1 local subscriber88.5K subscribers
                                                                                                                Mods: L3s@lemmy.world
                                                                                                                • BE: 1.0.0-beta.2
                                                                                                                • Modlog
                                                                                                                • Instances
                                                                                                                • Docs
                                                                                                                • Code
                                                                                                                • join-lemmy.org