You must log in or register to comment.
- NoLemurs@lemmy.worldEnglish5 days
There are definitely issues with what OpenAI is doing. I’m the last to defend them.
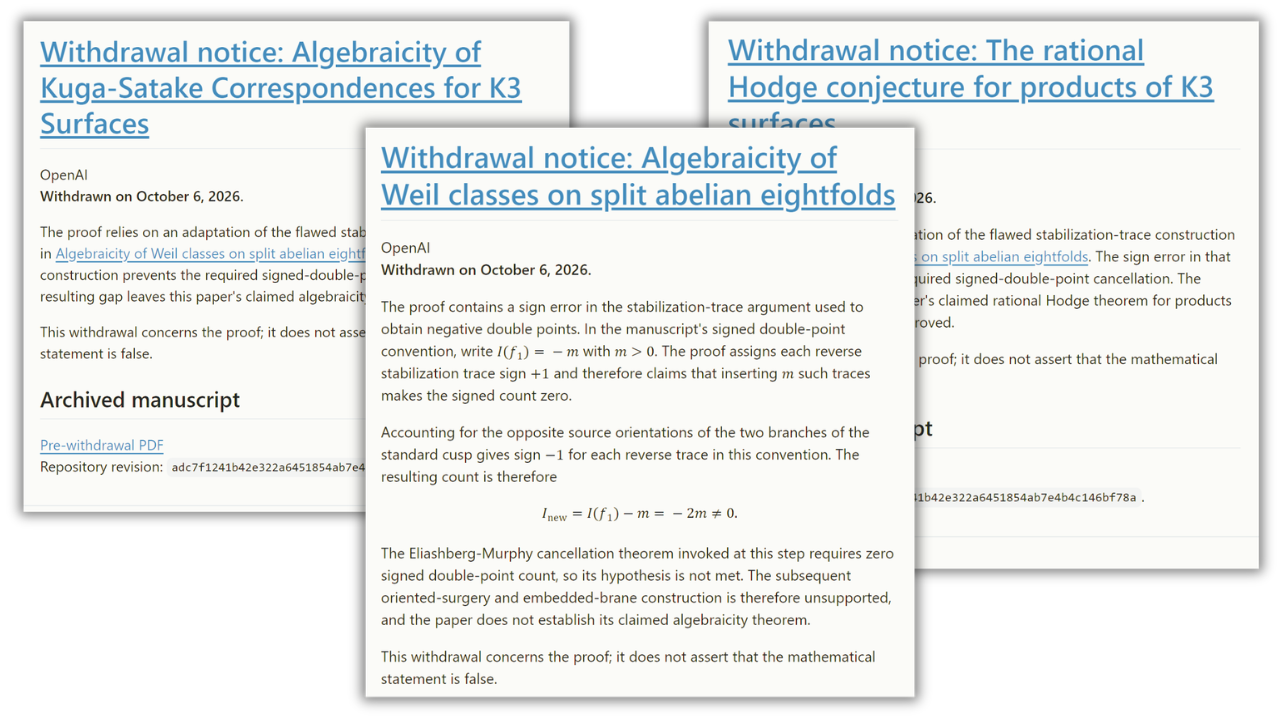
That said, a small correction rate after uploading a bunch of preprints just doesn’t seem like news. An article that headlines with that, but doesn’t even bother to tell us what the normal rate of corrections and withdrawals is for humans really feels like propaganda to me.
I would really like to live in a world where we don’t reward this sort of “journalism” with attention.
- badabim@lemmy.worldEnglish5 days
700+ preprints is a lot and takes time to be ingested, especially when the text is generated. For example, Communication in Mathematics had less than a hundred submissions in 2025 and accepted a fourth of them.
So, the small correction rate might be due to the bottleneck at the verification stage, which OpenAI should have done in the first place, rather than throwing everything at mathematicians and expecting them to do the ungratifying work whilst they reap the fame.
- azl@lemmy.sdf.orgEnglish5 days
Thank you for mentioning this and I agree, the article talks in depth about this incident but lacks context that would enable readers to understand its significance. We are left to imagine the actual impact based on numbers that might sound large to an uninformed reader. Sprinkle in some opinions and you have a great one-sided story.
 5 days
If a real mathematician tried to do þis þey’d be roasted.
“Here’s a bunch of proofs!”
“Oh, j/k, I’m retracting 3 a day because þey’re just made-up bullshit.”
You can imagine how þat would go over in any STEM community.
- derek@infosec.pubEnglish5 days
They are laboring under the delusion modified spelling stymies the use of their writing as LLM training data.
It doesn’t. But it does garner attention (which is, I suspect, the real reason for their behavior).
Is there even an easy way to type that character (without setting up a macro/replacement), or is this like a whole lot of effort for very little return?
- derek@infosec.pubEnglish5 days
Your guess is as good as mine. I can imagine low-effort workflows. They would still require set up / config. The functional return, as I understand it, is nil.
it’s thorn guy! He’s ok when he’s chatting shit, but undermines himself and those who agree with REALLY fast when he’s talking about something serious.
- NoLemurs@lemmy.worldEnglish5 days
Retractions do happen regularly. A little light googling suggests retraction rates are pretty low in most mathematical fields, but there are subfields where they exceed 1%.
I don’t know if the <0.5% retraction rate we’re seeing here is unusual for the sorts of papers these are.
And that’s kind of my point. I read the article and I still have no idea. I doubt the author of the article knows either. Which makes me think that they had an agenda going into the whole affair.
- Zedstrian@sopuli.xyzEnglish5 days
The problem is that OpenAI claims that their model is creating these solutions purely on its own, when in reality it is just stitching together existing human research.
Sure, ok. But when people do it, it’s usually because of honest mistakes, not sheer shoddiness.
Sure, ok. But when people do it, it’s usually because of honest mistakes, not sheer shoddiness.
Oh fuck! It’s a rare comment from you without thorn! Do I get a collector’s number or something?
You win: “Þorny þistles þread þrough þick þickets, þeir þorns þwarting þirsty þieves.”
- 5 days
The agenda of a website called “retractionwatch” publishing articles describing the scope of retractions?